
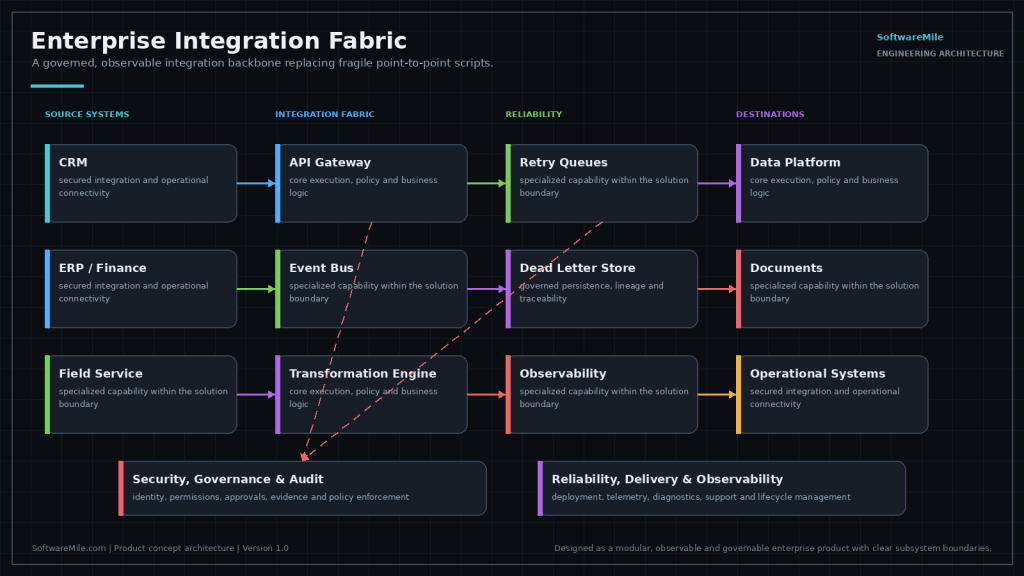
Most integration estates are not architected; they accumulate. A script here to sync customers, a scheduled export there, a webhook someone added in 2019 that nobody wants to touch. It works until it doesn’t, and when it fails it usually fails silently — discovered days later when two systems disagree about reality.
Status: product concept, in active development. This is something we are building, not something you can buy today. We publish our roadmap because the engineering thinking behind it is the useful part — and because we would rather show you the design than imply a finished product.
Designed Capabilities
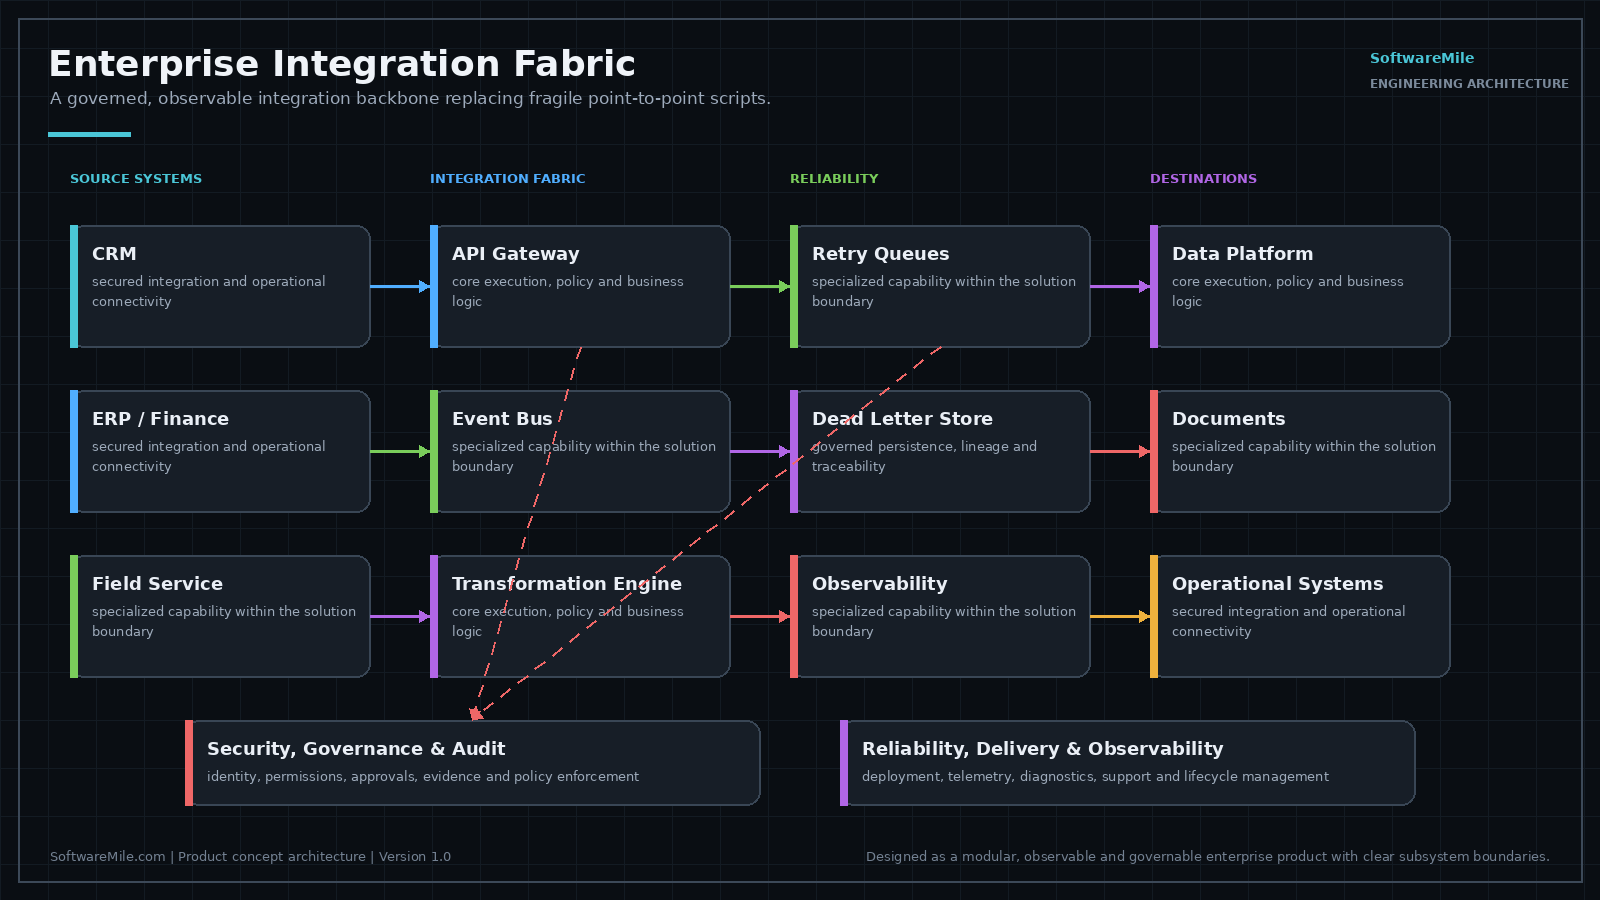
- API gateway and connector registry — one place that knows what is connected to what.
- Visual mapping and transformation studio — field mapping as configuration, not buried code.
- Event routing and durable queues — messages survive the downstream system being down.
- Credential vault and connection policies — secrets out of scripts and config files.
- Retry, replay and dead-letter operations — failures are visible and recoverable, not lost.
- Canonical data models — agree once what a customer is, rather than per-integration.
- Integration health and SLA monitoring — know it broke before the business does.
- Connector SDK and lifecycle management — new connections are built to a pattern.
The Point Is Observability
Point-to-point scripts are not bad because they are simple — they are bad because they are invisible. When an integration fails at 2am, the question is whether anyone finds out, whether the message is recoverable, and whether someone can replay it. Designing for that from the start is the difference between an integration layer and a pile of automation.
Tell us if this matches a problem you have — early input shapes what we build first, and we will give you an honest view of where it stands.
When an Integration Fabric Is the Wrong Answer
The honest test is count and coupling, not ambition. Two systems moving data in one direction do not need a fabric; a well-written scheduled job with real logging and an alert when it stops is a smaller thing to own and a smaller thing to explain to whoever inherits it. A platform is justified when nobody can hold the map in their head anymore, or when the same entity is being written by several scripts that quietly disagree about it. Below that threshold, a fabric adds a layer that has to be run, patched, and understood, and it buys observability you could have had more cheaply.
It is also the wrong answer when the problem is organizational rather than technical. If two departments genuinely disagree about what counts as an active account, no mapping studio settles that; the platform can only make the disagreement visible and assign an owner to it. That is worth something, but it is worth being clear that the fix is a decision, not a transformation rule. Integration work that starts without those decisions tends to encode one department's answer by accident and then defend it for years.
The third case is a single vendor already owning both ends. When two applications ship from the same suite with a supported connection between them, using that connection is cheaper than reimplementing it and easier to support when it breaks. A fabric earns its place at the seams between vendors, at homegrown applications, and at the connections nobody documented, not inside a boundary a vendor already maintains.
- Few connections, one direction, one owner: a scheduled job with alerting is usually enough.
- Many connections, shared entities, several teams writing the same records: the map itself becomes the problem a platform solves.
- Disagreement about what the data means: name the owner first, because no mapping layer can arbitrate it.
Canonical Models Are an Agreement Before They Are a Schema
The roadmap item above says agree once what a customer is. The ordering in that sentence is the whole point, because connectors written first encode assumptions that later have to be undone. Every point-to-point script already contains a private answer to what a customer is, what makes two records the same record, and which system is allowed to change an address. Those answers were never written down and they were never compared, which is how two systems end up both correct and contradictory.
Producing the agreement is not a modeling exercise an engineer can do alone with a schema editor. It needs a person per system who can say authoritatively which field is the real one and which values are legacy leftovers nobody has cleaned up. The hardest cases are fields that look identical and are not: two status fields with the same name and different lifecycles, or two identifiers that overlap for most records and diverge for the ones that matter. Discovering those during mapping is normal. Discovering them after go-live is what makes integration projects feel unpredictable.
A canonical model does not have to be complete to be useful, and trying to make it complete is a common way to stall. Only entities that cross a boundary need canonical form. Fields that one system uses and nobody else reads stay in that system, undescribed and unowned by the fabric, which keeps the model small enough that people will actually maintain it.
- Identity: which system issues the identifier, and how records are matched when it does not travel with them.
- Authority: which system is allowed to change which field, and what happens to a write that comes from anywhere else.
- Lifecycle: what states an entity can be in, and which transitions are legal, stated once instead of per integration.
Replacing an Estate Without a Cutover Weekend
Nothing about this design assumes a weekend where the old scripts stop and the new platform starts. The existing exports, webhooks, and scheduled jobs keep running while the fabric is being stood up, so the platform has to coexist with the things it will eventually replace. That constraint shapes the design rather than following from it: a flow is expected to run in parallel with the script it replaces, writing to a test target or writing nothing at all, while the two outputs are compared record by record.
The first flow to migrate should be chosen for verifiability, not value. Pick something low in volume, with a result someone can check by looking at it, and with a user who will say something if it is wrong. The instinct is to start with the flow that hurts most, but the flow that hurts most is usually the most coupled one, and it is a poor first test of a canonical model that has not been used yet. Once one flow has run through the model, the second is faster because the arguments about identity and authority were already had.
Retiring the old path is part of migrating the flow, not a follow-up task. A script left running beside a new flow will write the same record twice, or overwrite a field the new flow just corrected, and the resulting inconsistency looks like a platform bug. Removing the old path, revoking its credentials, and deleting its schedule is part of finishing a flow, not cleanup to do later. The credential vault helps here only if the old script's secrets were actually revoked rather than left valid in a config file somewhere.
Frequently Asked Questions
What is Enterprise Integration Fabric, concretely, and what is it not?
It is a platform that owns the connections between business systems: the roadmap items above, run as one platform instead of as scattered scripts with no shared registry, no shared model, and no shared way to see failure. It is not a data warehouse or a reporting pipeline, it is not a replacement for any application it connects to, and it is not a rewrite of your systems. It is also not a product you can buy: it is a concept in active development, so there is nothing to license, install, or deploy today.
What is it designed to run on, and what has to already exist on our side?
It is designed to run as a set of services near the systems it connects, on cloud infrastructure or on servers you operate, wherever it can reach both ends of every connection it manages. What has to exist first is on your side: systems that expose an API, a database, a file drop, or an event stream; network routes to reach them; and credentials that can be issued to a service rather than borrowed from a named person's login. A system with no programmable interface can only be integrated through whatever it does expose, usually a scheduled export, and that ceiling determines how current the data on the other side can be.
How is installation and rollout designed to proceed, in order?
The intended sequence is one flow at a time, never a platform-wide switch. First the platform is stood up in a non-production environment and connected to one source and one target so the connectors and credentials are proven in isolation. Then you choose one flow whose correctness is easy to verify, agree on the canonical shape for the entities it touches, build the mapping, and run it beside the existing script while comparing output. Only when the two agree does the old path get switched off and the next flow begin. This describes the design, not an installed system: the product is still in development and no rollout of it exists to schedule.
How would it integrate with the systems we are already running?
Through the connector registry and the connector SDK, so each system gets a connector built to a common pattern rather than a one-off script: what it reads, what it writes, and which credential it uses are described in one place instead of living in someone's code. Systems with documented APIs are the straightforward case. The work concentrates in older applications where the only integration point is a database table or a nightly file, and in homegrown applications where an API exists but its behavior was never written down. The connector is where that awkwardness is absorbed, so everything downstream sees the canonical model rather than each system's quirks.
Where does our data live, and what stays under our control?
The design moves data rather than accumulating a copy of it: messages pass through durable queues so they survive a downstream outage, and what persists afterward is the operational record needed to replay and troubleshoot a failure. How long that record is kept is your setting and a real decision, because a longer replay window means holding business data longer. Credentials sit in the vault instead of in scripts, and the connection policies that decide which connector may use which credential are defined by you. Because it is designed to run in infrastructure you control, the boundary of where the data goes is the boundary of that environment.
What do we have to provide or decide ourselves?
Access and authority, and neither can be delegated to us. Access means credentials, network routes, and a non-production copy of each system to test against, because verifying a flow by writing to production is not verification. Authority means a named person per system who can settle what a field means and which system wins when two systems disagree; without that person, mapping work stops on questions no engineer is entitled to answer. You also decide the order in which flows are migrated, which is a business judgment about which disagreements are costing you the most right now.
What commonly goes wrong with integrations, and how is that handled by design?
The common failures are dull ones: a downstream system is unavailable, a record arrives that does not fit the mapping, or the same event gets delivered twice. Durable queues cover the first, so a message waits instead of disappearing. The second is designed to land in a dead-letter queue where it can be inspected, corrected, and replayed, rather than surfacing days later as two systems disagreeing about reality. The third is the connector's responsibility: writes have to be built so that repeating one does not create a second record, which in practice means matching on a stable identifier before writing rather than inserting and hoping.
How does this relate to the integration work Software Mile does today?
Custom integration is engineering work we do now as project engagements: APIs, systems integration, and cloud architecture built for one client's estate. The fabric is an attempt to turn the parts of that work that repeat, the registry, the mapping, the retry and replay behavior, the health monitoring, into a product instead of rebuilding them each time. Until it exists, an integration problem is addressed as a build, though the thinking described on this page shapes how that build is structured. Nothing here should be read as a product you can adopt now.